Alvin C. Nataputra
Data Scientist / ML Engineer

I ask too many questions — then go build the answers.

Building quant models, agentic systems, and full-stack tools — one curious question at a time.

Explore projects Curriculum vitae (PDF) Say hello
Desk notes

“Why? How? What if?”

Taped above my monitor. Applies to a stack trace, a market signal, or an application essay.

Now
Building ML systems and agentic tools, prepping a Master's application (Europe).
Focus
ML systems engineering, agentic AI, applied forecasting/signal generation.
Location
Jakarta (GMT+7) · also open to remote opportunities.
01About

Curious brain, loves vibing.

Statistics, to make sense of an uncertain world. Code, to put it to use.

"

How I work

Keep problems small, prototype with real data, iterate. Listen before proposing — most solutions fail by solving the wrong problem. I'm comfortable deciding under uncertainty, and changing course when I'm wrong.

Preference: measurable claims. Every repository here states what it tested, what it did not, and what would break it.

Traits

  • Focus on Impact — curiosity, paired with action.
  • AB Tester — I test ideas rigorously.
  • Value Time — it's limited, so I prioritize.

Quick snapshot

  • Base Jakarta, open to remote pods.
  • Off-hours Coffee, JRPGs, playlists, slow mornings.
  • Pursuing A Master's in AI/ML.
02Capabilities

What I actually do

Hands-on with data — from understanding the problem to shipping the fix.

Data & ML craft

  • Modeling Gradient-boosted ensembles, calibrated classifiers.
  • Data engineering Idempotent ETL, data-quality gating.
  • LLM integration Multi-agent orchestration, agentic tools.

Product & engineering

  • Full-stack React/Next.js, FastAPI/Flask, dashboards.
  • CI/CD Test + lint gates on every push.
  • Documentation-first Repos legible to humans and agents alike.

Currently focused on

  • Agentic AI Keeping agents grounded over long autonomous runs.
  • Applied ML Forecasting and risk modeling under real constraints.
  • Grad school A Master's application in AI (Europe).
Roles
Data scientist · ML engineer · ML systems engineering.
Side projects
Quant trading ML, agentic orchestration, full-stack apps.
Open to
Remote-first roles and collaborations across time zones.
03Side Projects

Recent builds & experiments

Projects that blend statistical intuition, machine learning, and thoughtful product craft.

project-aurum research

Project Aurum — Quant Trading System

Ensemble ML signal generation (LightGBM + XGBoost + Random Forest) for the Indonesian Stock Exchange, with triple-barrier labeling and walk-forward CV with embargo (per López de Prado's AFML). Trained on 2020–2024, evaluated out-of-sample on full-year 2025 IDX data. Team project, 4 contributors.

+0.12%
strategy
+14.17%
buy & hold
+20.71%
IHSG
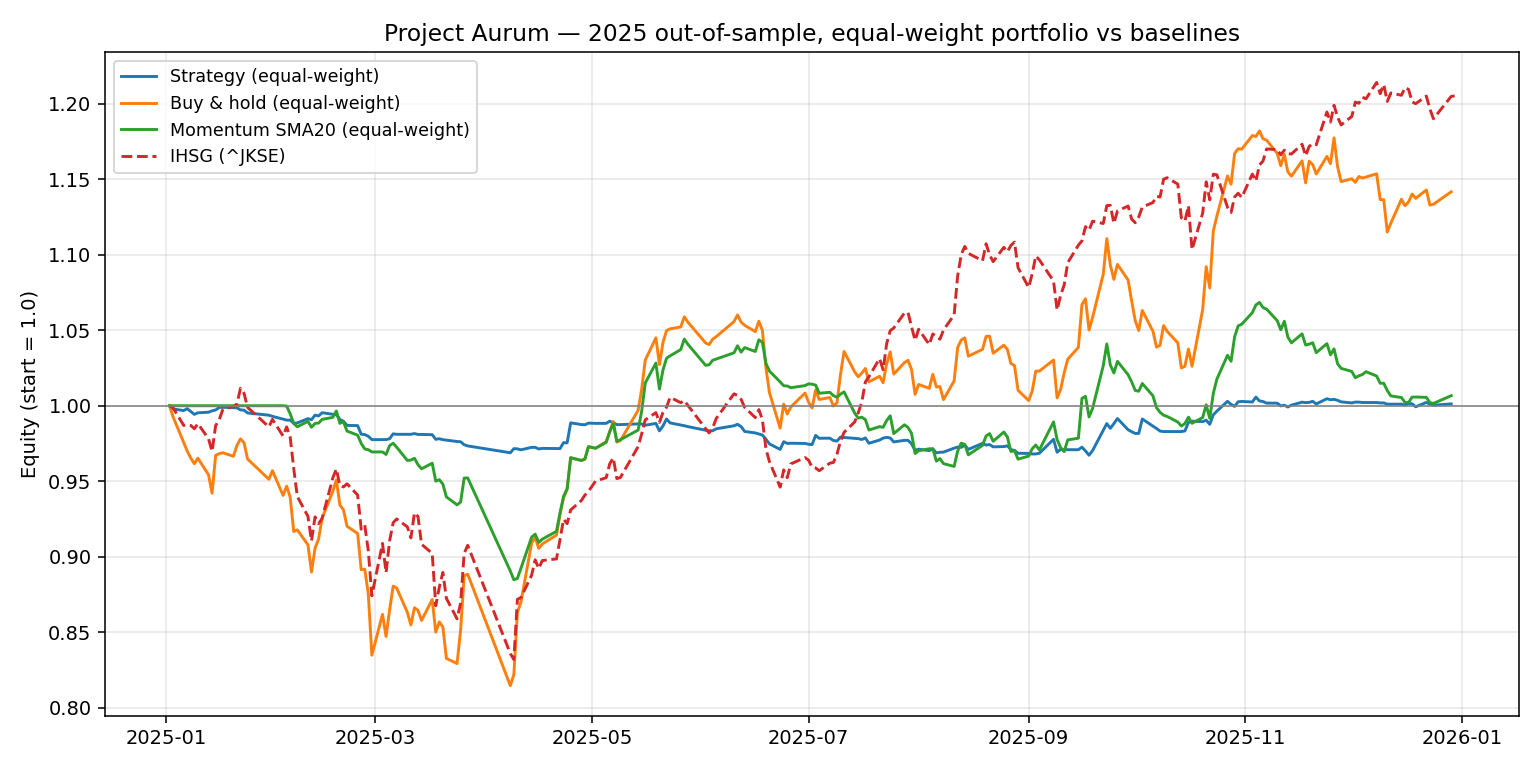
Re-evaluated without leakage: the model does not beat buy-and-hold, and walk-forward accuracy (0.34–0.36) falls below the 0.53 majority-class baseline. The earlier 195% / 2.70 Sharpe result is withdrawn — four evaluation defects account for it. Code, run manifests and figures are in research/.
  • LightGBM
  • FastAPI
  • React
suicide-detection research

What a 0.91 F1 actually measures

A leakage audit of the undergraduate Indonesian suicide-ideation corpus. A random 80/20 split without deduplication put 36.5% of the validation posts in both halves. Research/educational — not a clinical tool.

36.5%
val leaked
0.910
F1 published
0.849
F1 clean retrain
Scored on unseen rows: 0.877. Retrained on a deduplicated split, so the weights never see the twins: 0.849 [0.821, 0.877] against 0.785 for the strongest baseline — a +0.064 advantage (McNemar p=0.015), about half what the published pair implied.
  • NLP
  • IndoBERT
  • evaluation
orchestrator-system self-hosted

Autonomous Agent Orchestrator

Self-hosted coding agent that runs on a cron/systemd schedule: hybrid RAG context retrieval, failure memory, LLM-as-judge output scoring, reversibility classification before destructive ops, and automatic commit/PR workflow.

7
Task types
5
DB tables
  • RAG
  • PostgreSQL
  • Claude Code CLI
Explore project →
More builds
Telco CVM Analytics & ML Lab Idempotent DuckDB warehouse ETL with a data-quality gate, dual calibrated risk models (churn AUC 0.823, late-payment AUC 0.628), and LLM-narrative ops reporting — IBM Telco dataset + a synthetic 1M-row usage stream. Explore project →
LapScout — Indonesian Laptop Finder 800+ laptop models scraped from Indonesian retailers, normalized through a three-layer medallion pipeline, with an AI chat advisor (Maki) that translates natural-language queries into live database lookups. private repo
Telco Churn — Causal Inference XGBoost churn model with SHAP, plus an IPTW causal layer isolating product adoption's actual effect on churn, revenue, and CLTV — Indonesian telco dataset. Team project with an interactive Streamlit dashboard. Explore project →
Turning-Point Analysis Bull/bear market phase dating for IDX stocks via a Pagan-Sossounov style censored local-extrema algorithm — no arbitrary fixed lookback window. Explore project →
Speech Event Study Rebuilt as a proper event study: the original join had 32 news rows and zero abnormal labels, so it could not have shown anything. News as event gives 26 events, Patell Z −2.84 (p=0.0045), 1/26 surviving FDR correction. Explore project →
BRImo Sentiment Sentiment analysis on public BRImo Play Store reviews — local LLM (Ollama, llama3) extracts topic, sentiment, and explanation per review at corpus scale. Explore project →
04Research

The result I did not want

My quant project reported a 2.70 Sharpe and 195% return. That number had no run artifact behind it, so I rebuilt the evaluation from scratch — purge, embargo, fold-local scaling, sample weights, and baselines under identical costs. With the leakage gone, the strategy stops beating buy-and-hold. That is a more useful thing to have found than the number it replaced, and the write-up, code, manifests and figures are all public.

Four defects in the original evaluation

  • In-sample "test" data — the final model was trained on rows spanning the 2025 test window.
  • Selected on test — walk-forward early stopping used the fold's own test set.
  • Whole-series scaling — the scaler was fitted before any split.
  • Embargo too short — 5 calendar days against a 10-trading-bar label horizon, with no purging of overlapping labels.

What the corrected run says

  • Equal-weight, 16 IDX large caps, 2025 out-of-sample, net of IDX costs.
  • +0.12% signal model with the meta-labeler filter · +7.62% without it · +4.73% technical features only.
  • +14.17% buy & hold · +20.71% IHSG.
  • Walk-forward accuracy 0.34–0.36 against a 0.53 majority-class baseline — worse than always predicting the most common label.
  • The meta-labeler reduces exposure, not risk per unit of return: it cut return from +7.62% to +0.12%.
2025 out-of-sample equity curves: signal model, buy and hold, momentum SMA20, and the IHSG index
2025 out-of-sample equity curves, start = 1.0. The strategy line stays flat while buy-and-hold and the index climb. Reproduced by research/aurum_experiment.py.
Read the write-up → Evaluation code and run manifests →

And the 0.91 F1 that was also inflated

The undergraduate suicide-ideation corpus is a scraped X sample. A random 80/20 split without deduplication put 739 of 2,026 validation posts (36.5%) in both halves. On the 1,287 genuinely unseen rows, fine-tuned IndoBERT falls from F1 0.910 to 0.877 [0.845, 0.904]. A character n-gram logistic regression reaches 0.787; the remaining transformer advantage is +0.090 [+0.049, +0.131]. The FastText + LSTM thesis arm cannot be recomputed — tokenizer and vectors were never saved — and that is recorded rather than hidden.
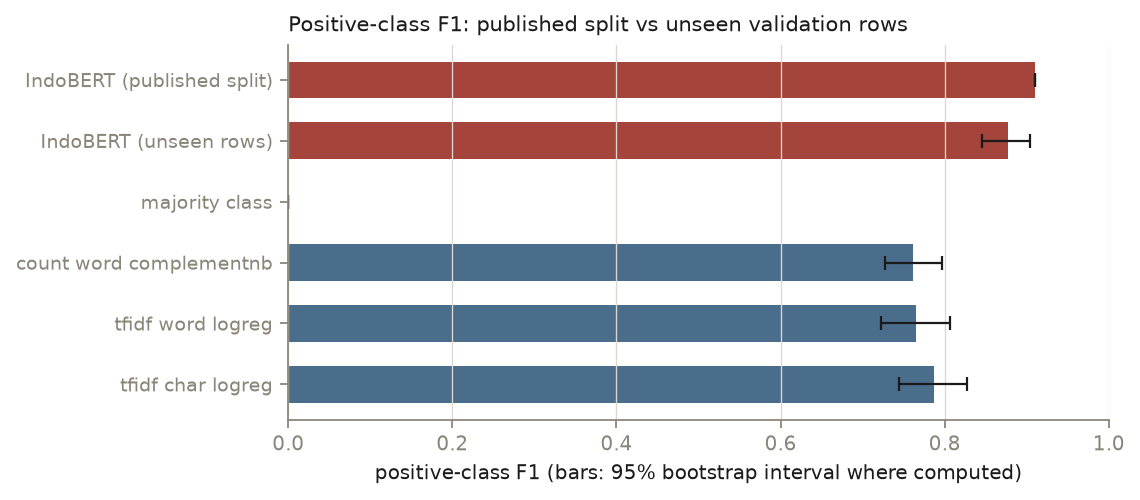
Positive-class F1 by protocol: published split versus unseen validation rows, with cheap classical baselines
Positive-class F1. Error bars are 95% bootstrap intervals on unseen rows. Reproduced by eval/si_eval/run.py.
Read the paper → Evaluation code →
05Notes

What I'm noodling on

Directions I keep returning to. Where one has produced a result, it is a public artifact rather than a post — a leakage audit, an IDX re-evaluation — linked above.

Agentic AI groundedness

Keeping an agent from drifting over long autonomous runs. I'm testing a self-hosted stack that observes itself and learns from its traces — the hard part is knowing when to trust its judgment.

ML under distribution shift

Most ML systems are tested on data from the same distribution as training. In production — especially markets — that distribution keeps shifting. The real question is detecting it early enough to act.

Building with Indonesian data

Most ML tooling assumes English-first data and deep markets. Bahasa Indonesia NLP and the Indonesian equity market mean thin data and constant regime change — constraints that force cleaner thinking.